Today we’re releasing SuperNet-202, an update to our OCR model for
v3/text, v3/pdf and the Files API. It focuses on recognition accuracy, with a few new symbols and a set of smaller fixes. The improvements apply automatically, with no changes to your requests.Better recognition
Dense pages such as newspapers are recognized more completely, with less missing text. Vertical Chinese and Japanese text is recognized more accurately on complex vertical layouts. Portuguese ordinal indicators such as
º and ª are now recognized on low-resolution and complex pages as well.Checkboxes and radio buttons are recognized more accurately. Longer lines of text are now recognized as text instead of being returned as images; very long lines are still returned as images.
New symbols
Keyboard shortcuts keep their key symbols, such as
⌘+⇧+3, ⌘+⇧+4 and ⌘+⇧+5.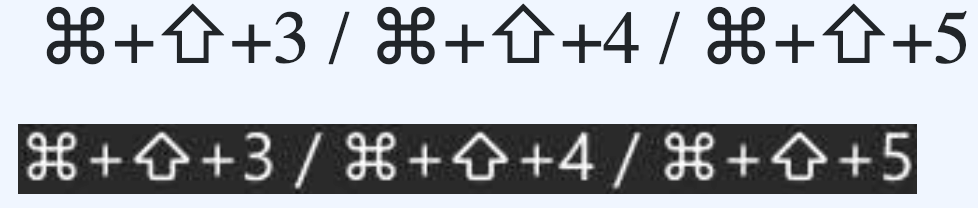
The OCR output (top) keeps the key symbols of the source image (bottom).
Up, down and equal indicators in tables,
△, ▽ and ◇, are recognized as symbols, including colored and filled versions.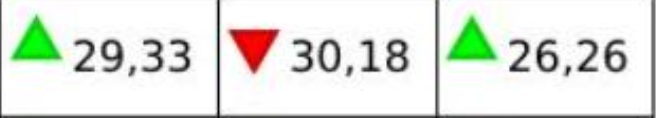
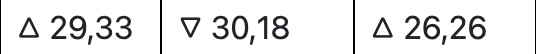
Colored indicators in the source table (top) are recognized as
△ and ▽ in the OCR output (bottom).Other fixes
- Equation numbers are no longer lost, and adding them no longer produces invalid LaTeX.
- Short, single-line figure captions no longer run into nearby text.
- Lines in table cells on curved pages stay in reading order.
- Diagonally split table cells keep both of their labels.
- In a table of contents, a page number follows its title when the title wraps onto a second line.
- Paragraphs in table footnotes stay separate.
- Region coordinates no longer extend past the page edge, and regions outside the page are no longer returned as empty images.
- Fixed a rare case where the same region was returned many times.
Change to line data
Page columns are no longer returned as separate regions. Line data no longer includes entries of type
column, and the column field of every line in lines.json and lines.mmd.json is now 0. Lines are still listed in reading order, each with its region, so columns can be derived from line positions. Table columns are unchanged.See the changelog for release details. Please reach out to support@mathpix.com if you have any questions.