Best Practices
Minimizing latency
The biggest source of latency is image uploads. The speed of a response from Mathpix API servers is roughly proportional to the size of the image. Try to use images under 100KB for maximum speeds. JPEG compression and image downsizing are recommended to ensure lowest possible latencies. For minimal latencies, we also recommend using form uploads with a file and a
options_json form field instead of using base64 JSON encoding for image data (both options for sending an image are described in https://docs.mathpix.com/guides/image-ocr). We also recommend using an easy-to-use cropping UI for end users to crop images, so that the minimal amount of image data is send to the API.Server locations
The global
api.mathpix.com endpoint is served from US East 1 (N. Virginia).To optimize latency, we recommend co-locating your infrastructure near that region.
If you are located in the EU, or you need your document data to be processed and stored within the EU, send requests to our EU endpoint
https://eu.api.mathpix.com/. Everything derived from your documents is processed and stored in EU data centers, and EU-processed results are queryable only from that endpoint. See EU data residency for details.Authorization
Mathpix OCR API currently offers API key authorization through a customer’s proxy server or the use of client-side app tokens.
We have always discouraged customers from putting API keys inside client-side apps, due to the risk of API key theft (note: customers are responsible for any usage made with a stolen API key). With app tokens, you can safely grant access to Mathpix OCR API services inside client apps, with a temporary access token that expires in five minutes (this is the default, the expiration is configurable). This way, you can keep your API key safe in your private cloud, and expose a single authenticated endpoint to your customers so that they can request and receive Mathpix app tokens.
This is convenient for taking advantage of our latency-routed global network of servers without needing to maintain proxy servers that are themselves also distributed globally. This also means that requests are faster because there is one less hop required to reach Mathpix OCR API servers.
Example configuration 1: Proxy server
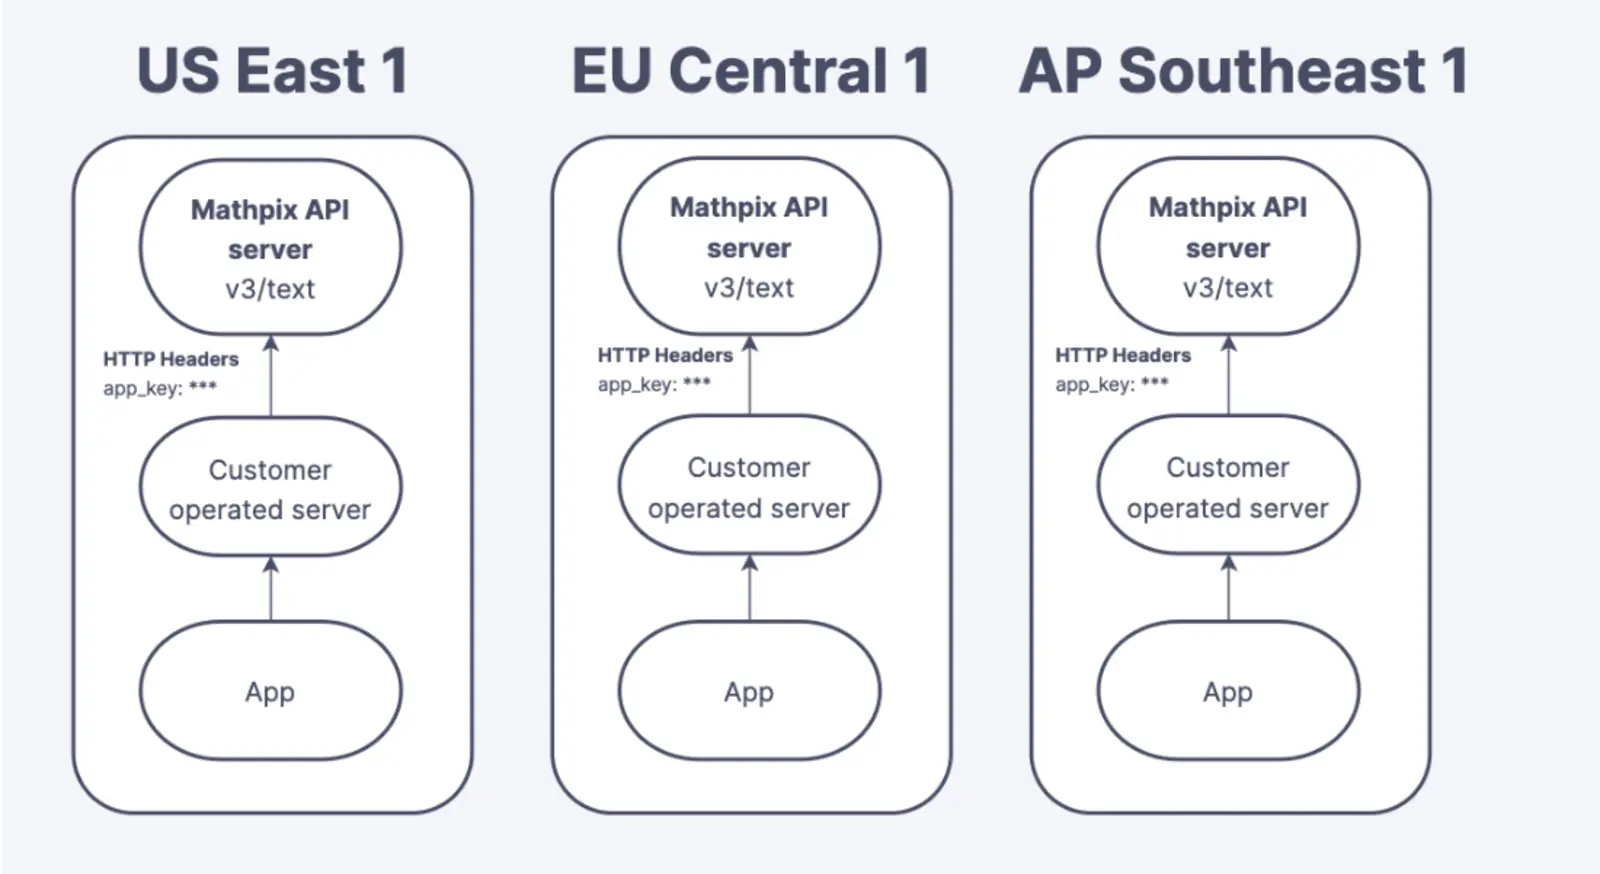
In the below diagram, the customer operates latency routed servers in each region to authorize requests and take advantage of Mathpix global network of servers. All app requests, including ones containing digital ink or image data, are proxied through customer operated servers.
Example configuration 2: App tokens
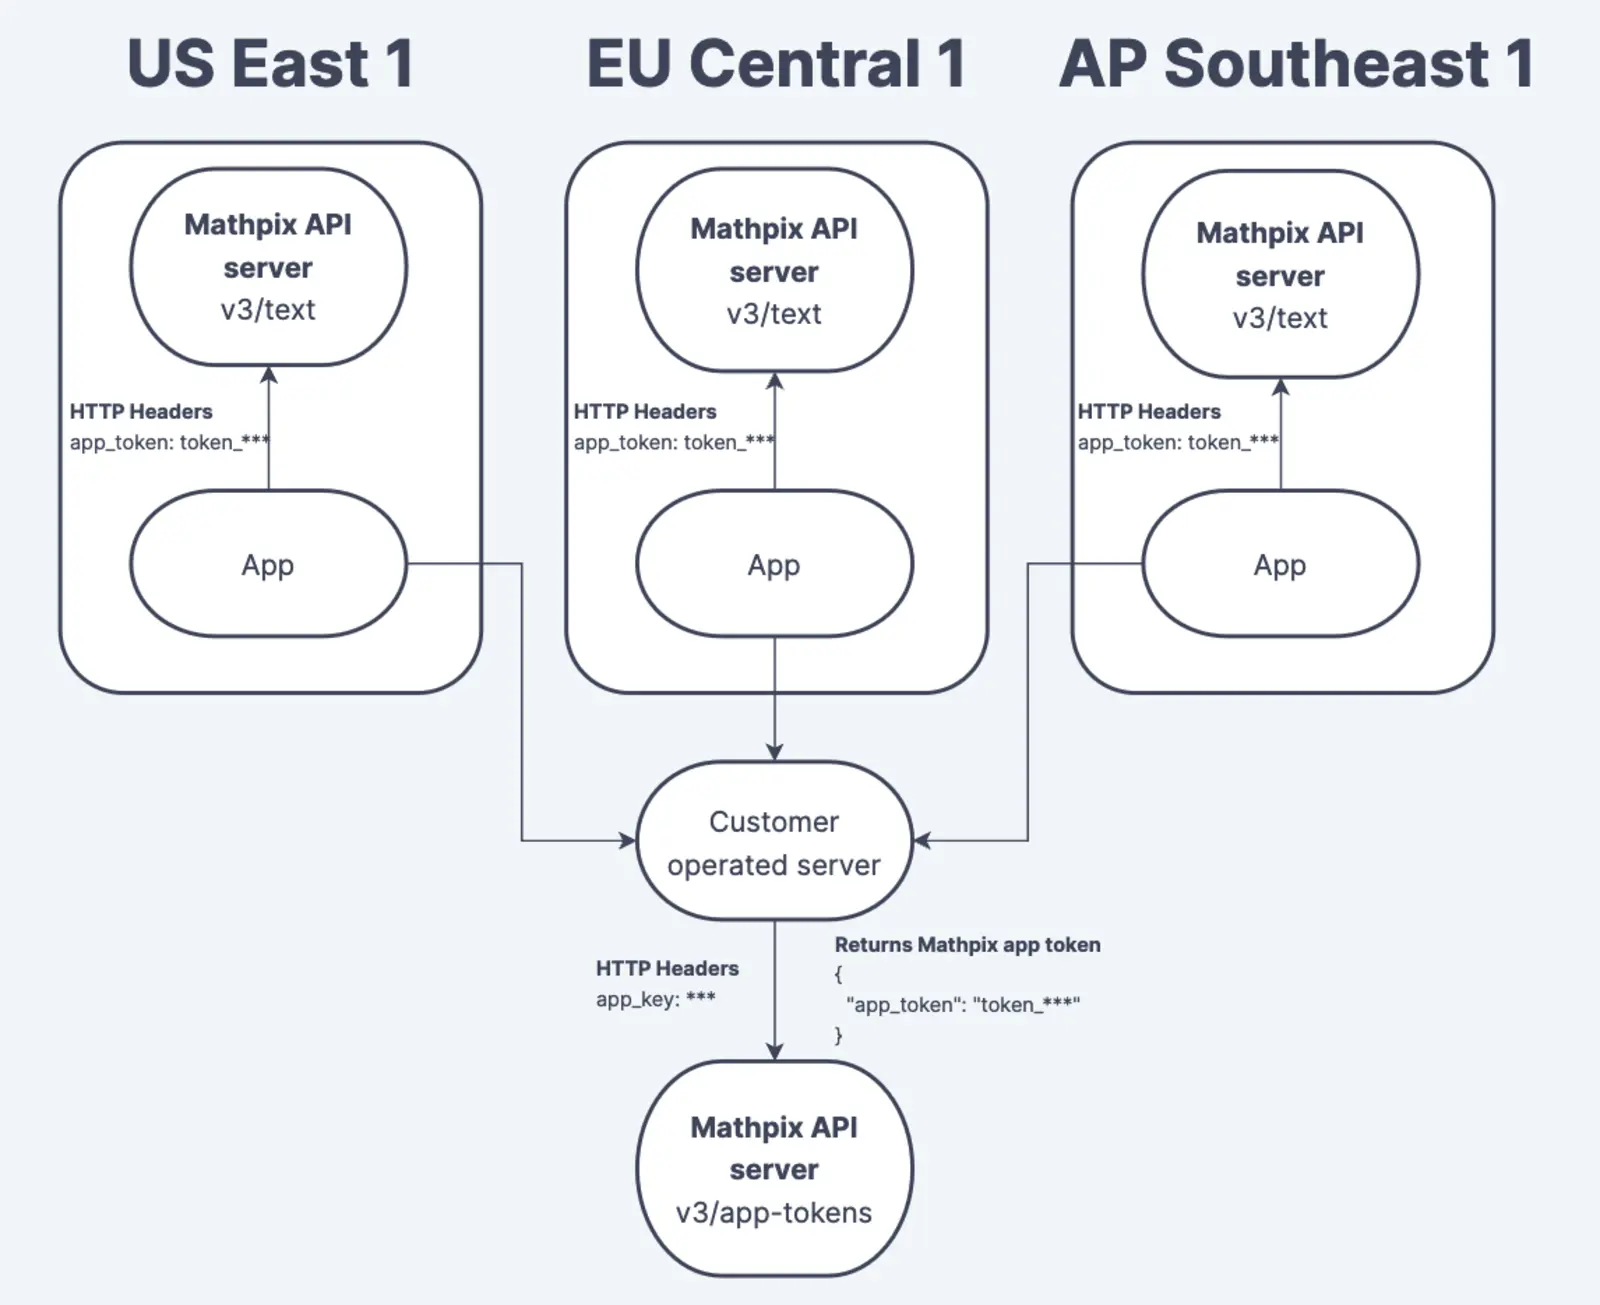
Now we show the same setup using app tokens. The customer operated server is only needed to fetch app tokens and does not need to proxy requests containing digital ink or image data. Customer API keys are only used to fetch app tokens. Apps can call Mathpix endpoints directly without having to go through an auth proxy.
Running “batch” / indexing jobs
For such use cases, we recommend using our v3/text endpoint with the “async” flag as well as leveraging the “tags” field (https://docs.mathpix.com/reference/post-v3-text#request-parameters). You can then query results later using our v3/ocr-results endpoints (https://docs.mathpix.com/reference/image-results) and specifying the same “tags” you used to call the v3/text endpoint. This method conveniently doesn’t require the API client to pre-batch requests at all.
v3/batch is the alternative when you would rather submit discrete batches and poll one batch ID. It defaults to v3/latex behavior, but setting ocr_behavior to "text" — per batch or per image — gives you v3/text behavior there too, so choosing it does not cost you full text recognition. See Use v3/text behavior.That advice is about images. If you are indexing documents rather than images, use the Files API instead. It takes up to 200,000 documents in a single job, reads from and writes to your own S3, GCS, or Azure storage, and is billed at a lower per-page rate than
v3/pdf. Polling per document, or fanning out one v3/pdf call per file, is the slower and more expensive way to do the same thing.For monitoring request volume and cost spikes during long-running jobs, configure per-key alerts on the Console Usage tab — see Usage alerts. Set a daily burn-rate threshold before you start a large job rather than after.
Persisting images from processed documents
When you process documents via
v3/pdf, the output Mathpix Markdown (MMD) contains embedded cdn.mathpix.com/cropped/... URLs that point to page images on Mathpix servers. Those page images are retained for up to 30 days by default.For long-term image access, request a zip output format at processing time — the zip embeds all referenced images inline and is self-contained:
{
  "url": "https://example.com/your-document.pdf",
  "conversion_formats": {
    "mmd.zip": true,
    "docx": true
  }
}
Supported zip/bundled formats:
.mmd.zip, .md.zip, .html.zip, .tex.zip, .docx, .pptx. See the Data Retention page for the full retention matrix and how to request extended retention on your account.v3/text vs. v3/latex
Our first endpoints v3/latex and v3/batch were based on image to LaTeX conversion, where the intent was to parse out the math in an image, while ignoring text.
In order to provide better functionality for full text recognition, we build the v3/text endpoint, while keeping the v3/latex interface identical for backward compatibility. New customers should use v3/text endpoint as it has more features and is more robust.
Supported file types
Images are decoded with OpenCV, so the common raster formats all work, and
v3/pdf accepts considerably more than PDF.The authoritative list of accepted inputs — images, documents, and markdown — plus every output format you can convert to, is Supported Formats. Check it there rather than assuming from this page; it is maintained alongside the code that does the decoding.
Using the Python SDK
If you are working in Python, mpxpy handles authentication, status polling, and result downloads for you, which removes most of the code where integrations get these best practices wrong. Install it with
pip install mpxpy and see Getting Started.